Most companies feel pretty good when they finally have a data catalogue. Thousands of tables are documented. Owners are assigned. Business terms are defined. Teams finally have one place to search when they need to understand where a piece of data lives.
For a while, it works.
Then the environment starts changing. A source system adds a new field. A pipeline gets rewritten. A table is renamed. Someone changes ownership of a dataset. A dashboard gets rebuilt against a different source. A new data product starts consuming information that nobody thought to document.
The catalogue doesn't know any of this unless someone updates it.
And that's where the problem begins.
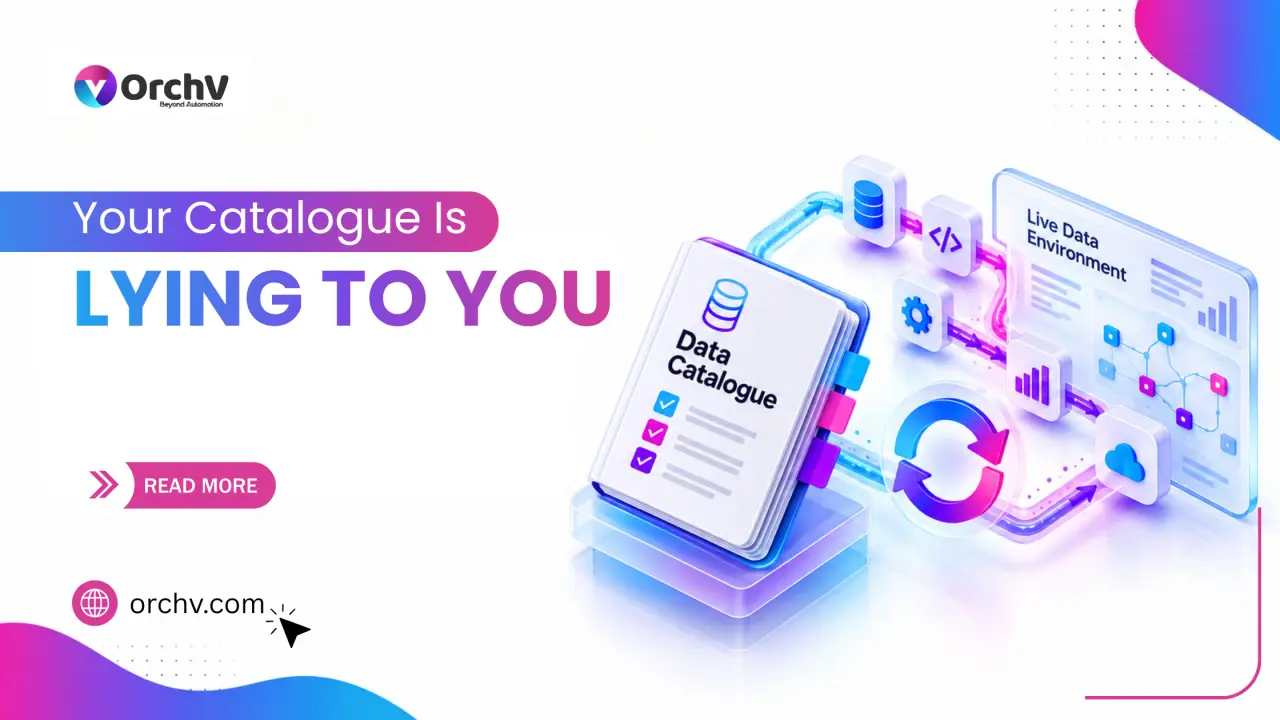
The catalogue may still look complete. It may have thousands of assets, beautifully described and neatly organized. But the question isn't whether the catalogue contains a lot of information. The question is whether that information still reflects reality.
A data catalogue is fundamentally an inventory. It tells you what exists, where it lives, who owns it, and sometimes what it means. That's useful, but it doesn't tell the whole story.
Imagine a finance team discovers that a number on an executive dashboard suddenly looks wrong. The catalogue might tell them which dataset powers the dashboard. But what they really need to know is where that number came from.
Which source produced it? Which pipelines transformed it? Which fields contributed to it? What changed upstream? Which other dashboards or models depend on the same data?
That's where lineage becomes important.
A catalogue tells you what exists. Lineage tells you how it got there.
And the difference matters more as enterprise data environments become more complex.
A catalogue can be perfectly accurate on the day it goes live and gradually become less useful as new systems, pipelines, schemas and business processes are introduced.
There is often an assumption that someone will keep the documentation updated. In reality, data teams are usually busy keeping the data itself running.
A new pipeline gets deployed. A schema changes. A field is deprecated. A new source is added. An ownership structure changes. The business moves on.
The catalogue is left behind.
This is why the idea of active metadata is becoming increasingly important.
Instead of treating metadata as documentation that someone updates periodically, active metadata treats it as something that should continuously reflect what is happening across the data environment. Schema changes, lineage, data quality, usage, ownership, classifications and pipeline activity can all become signals.
The difference is subtle but important.
A static catalogue tells you: “This is what we know about our data.” Active metadata moves toward: “This is what is happening to our data right now.”
That shift becomes even more important as AI enters the enterprise.
An analyst working with an outdated dataset might notice something looks wrong and investigate. An AI system may not. If an AI application is given outdated, incorrectly classified or poorly governed information, it can use that information as context and produce an answer that looks perfectly reasonable.
The model may not be the problem. The context was.
This is why metadata is becoming more than a discovery tool. It is increasingly part of the foundation that helps people, applications, and AI systems understand enterprise data.
The goal shouldn't simply be to have a catalogue with thousands of assets. It should be to have a reliable understanding of where data comes from, how it changes, who owns it, where it is being used, and what depends on it.
That requires more than documentation. It requires connection.
Connect the catalogue to the systems producing the data. Capture lineage automatically where possible. Track schema changes. Monitor data quality and freshness. Keep ownership and classifications current. Make governance signals part of the same environment rather than separate documents that nobody checks until an audit arrives.
Because the real value of governance isn't knowing that a dataset exists, it's being able to answer what happens when something changes.
A critical field changes today. Do you know what breaks? A new data source is introduced. Do you know which AI systems can access it? A dashboard reports an unexpected number. Can you trace that number back to its source? An auditor asks who owns a sensitive dataset. Can you produce the evidence without spending two weeks searching across spreadsheets and documentation?
Those are the questions a modern data governance strategy needs to answer.
The future isn't about building a bigger catalogue. It's about building a living understanding of the data estate.
Because data doesn't stay still, your governance shouldn't either.
If your catalogue tells you what existed yesterday, but not what is changing today, it's time to rethink what your metadata is really doing.
At **OrchV**, we help enterprises build stronger foundations across Data Engineering, Data Governance, AI, and Cybersecurity so their data isn't just documented, but trusted, traceable, and ready for what comes next.
Is your data catalogue keeping up with your data or is your data already ahead of it?
Tell us what you are working on, and one of our engineers will reply.